No engineering background. I built ThinkingAI a custom CMS anyway
Blog and news lived in one mixed type with no real publishing workflow, the sitemap was wrong, slugs were broken. I designed and hand-coded the replacement solo on Sanity: nine content types on a block system that demand generation runs on.
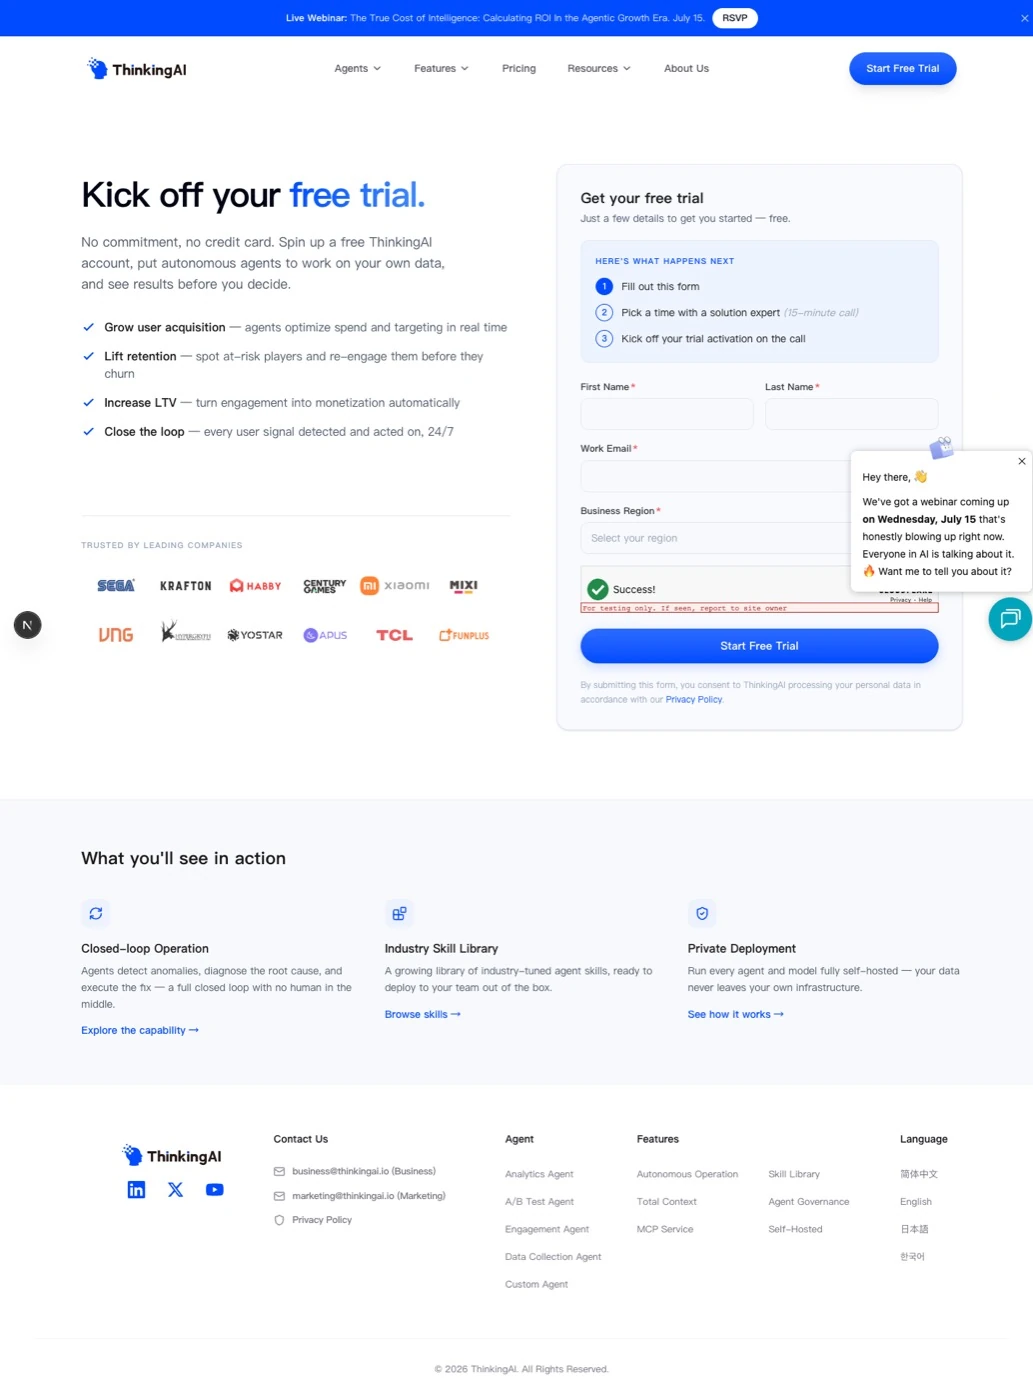
The old site blocked demand generation on every axis
One team runs four sites here: Japan, Korea, China and English. The sites themselves shipped fast, built with web coding and AI assistance, and underneath them there was no CMS. Every piece of content lived in a single blog tab.
- One tab held four different things. PR articles, news, product updates and blog posts all filed as the same content type, so the signal a visitor got was mixed at the source, and nobody could govern it.
- No funnel layers. No top, middle, or bottom-funnel content structure, and no modules to carry any of it.
- Broken plumbing. The sitemap was wrong and static, and slugs were broken. Both are SEO and routing liabilities.
- Bare-bones UX. The front end was basic enough that it undercut the brand it was supposed to sell.
The replacement runs as a pilot on the US site. Japan, Korea and China have not migrated onto it.
I had seen most of this before my first day, which is its own story.
I ran my own tool on the company before the interview
Everyone researches a company before an interview. I ran TechSpy on them, the competitor tech-stack tool I built for this kind of question. It read their public technical footprint: the stack behind the sites, DNS records, email sending setup, what was serving the content, and what the technical SEO looked like from the outside.
From that I could infer the shape of the problem before anyone described it to me: how content was probably being managed, where the workflow was likely to hurt, and which parts of the marketing site were quietly costing them. So in the interview I was talking about their actual situation instead of asking to hear about it. Six rounds were scheduled. The offer came after four.
The diagnosis in the section above is the one I walked in with, confirmed from the insideI hand-coded this platform from schema to frontend
I built it on Sanity, headless, feeding a Next.js 16 site that exports static and reads content at build time. Nine content types run on a reusable block system, we own the lead capture, and I hand-built the Studio the editors work in.
From one mixed blog to six editorial programs
Before, blog posts and PR announcements shared one content type. A visit told you nothing, because the signal was mixed at the source. I rebuilt it as six separate programs, each with its own funnel stage, strategy and conversion action: blog, newsroom and product updates work top-of-funnel toward newsletter signup; ebooks and webinars sit mid-funnel behind an email gate; customer stories carry bottom-funnel proof toward the demo.
Splitting them does two jobs at once. Navigation gets honest: each section is one kind of content with one purpose. And a product-led journey gets fed properly: a customer moving from first touch to using the product needs different content at every step, and the model now has a typed home for each of them.
newsroom absorbs external press via a newsType radio, so media mentions don't need a fake blog postEvery form feeds attribution into the CRM
Every CMS form validates in two layers before a lead ever exists: a work-email check that prompts on public domains, and hints inline when someone mistypes an address. Behind that, a Cloudflare Turnstile Worker proxy checks the demo form for bots server-side, layered with a honeypot and a blocklist.
Every form carries hidden fields recording the landing page, the full UTM set and the ad IDs (gclid, li_fat_id). I capture that on arrival, hold it in sessionStorage for the browsing session, then replay it at submit through HubSpot's Forms API into the CRM. There the automations pick the lead up, route it, run workflows and stamp the source, so I can see which page converted and which campaign paid for it.
Attribution survives the whole journey, from landing page to whichever page the visitor converts onRestyle the site's top line with no code deploy
A CMS-controlled bar pinned above the nav. Marketers toggle it, edit the message, and restyle it from 15 curated themes, 2 sizes, and 3 button styles. No code deploy. A custom Studio input shows a live WYSIWYG preview before publishing, and the change is live on the site a few minutes later.
One --banner-offset token, inlined on <html> during SSR, re-flows the whole layout with no first-paint jumpArticles went from plain text to composed pages
The old body field held plain text. Now every type renders through a typed block palette (inline CTAs, embedded video, tables, FAQs, pull quotes, stat highlights), and long-form pages carry a sticky right column with anchor navigation, so a reader can jump the article instead of scrolling it. Every block is a governed React component; there is no WYSIWYG blob.
caseStudy carries a structured metrics[] array plus a customer quote. BOFU proof is a field type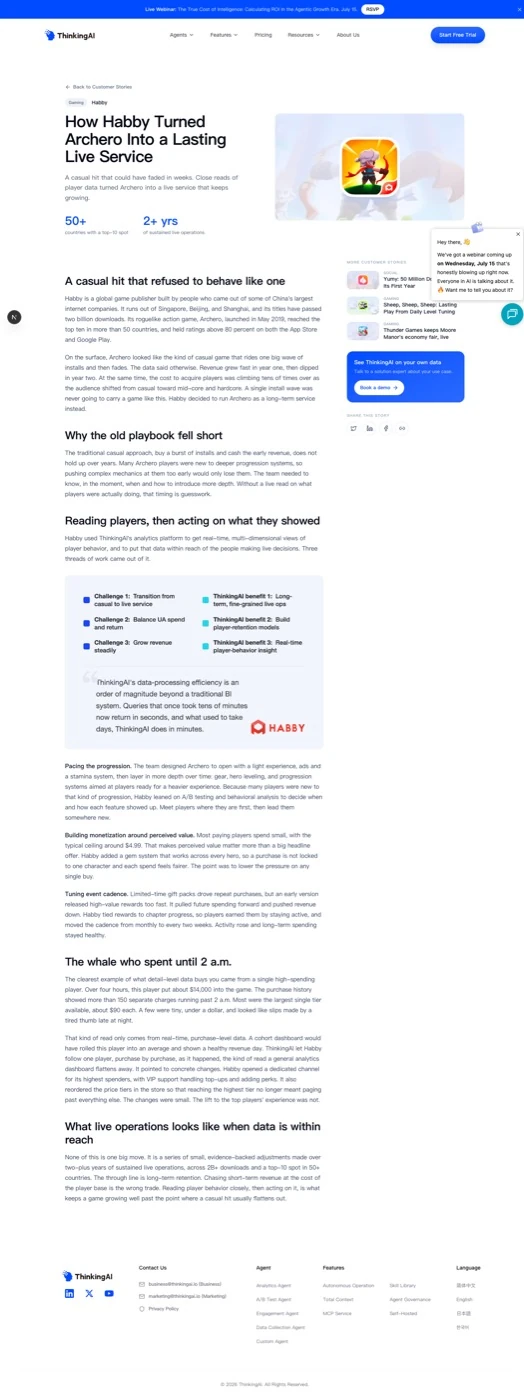
Build-time GROQ, static export, secret-free
A read-only, token-less Sanity client runs GROQ at build time inside server components; the projection shapes it, so React gets flat objects. Static export emits plain HTML: fast, secret-free, deployable to any static host including China. The sitemap and robots are CMS-fed and dynamic, fixing the old broken one. The China dev team deploys and runs the publish webhook.
A toSanityLang() bridge maps next-intl locales to Studio languages; one Sanity project per region keeps each editor's Studio isolated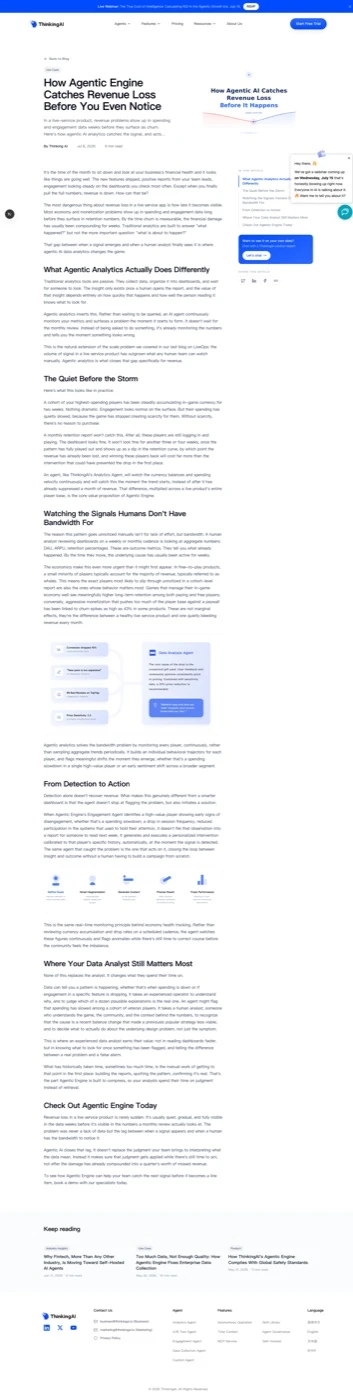
Every content type has a production line behind it
One person can keep the English site and its six editorial programs fed because each type has its own multi-agent workflow behind it, running from research through to the published page.
I open a piece at roughly 85% draft and finish it
For a blog post the chain runs competitor research, keyword research, brainstorm, outline, draft, then the visual and UX pass. On-page and technical SEO get their own steps inside the same run. Each stage is a different agent with its own brief. Feature image and banner are generated in the run too.
That gets a piece to roughly 85% by my estimate. I finish the part that has to be human: I strip the AI flavor out and push the depth up until it holds in front of a domain-expert audience. Two content types run further than that. News and product updates are automated, around 99%, because the source material is factual and the format is fixed.
Both percentages are my own estimates. I have not measured it formally, and nothing ships without a human passProduce, publish, then turn one piece into the next three
I paired each production workflow with a publish workflow: the one that writes a blog post files it into the CMS with fields, blocks, SEO and attribution already set. From there the same piece converts onward into a social post and a newsletter feature, so one production run feeds several channels instead of starting three separate jobs.
I attach attribution at the content layer, so every type can be traced through to the CRM. Across the six programs, research feeds production, production hands the piece to publishing, and publishing feeds distribution. The content manager left a month after I joined, so the editorial side has been mine since. Each piece has a defined path through these workflows, and the agents carry the drafting, so my hours go to the review. The agent teams behind these runs follow the reusable pattern in Capstone · Agent Systems.
Six programs, each with a paired production and publish workflow, all attributed back to the CRMThe numbers so far
The architecture is recent and not yet live on production, so these are the baseline, plus where it is heading. Every number here is screenshot-backed. I claim no lift from any of them yet.
What the content team got
HubSpot holds 5,749 contacts, 2,002 of them added in the last ninety days. Most of that window predates me and predates this system; the capture and UTM layer instruments the flow from here on, with the Turnstile/Worker gate guarding quality.
Search footprint
Q2 organic impressions went 1,253 in April to 24,847 in June. I inherited that window and cannot claim it. It is the baseline the new structure builds on. The same widening of the query set pulls average position from 4.6 to ~14.6.
What I can't claim yet
I started mid-June 2026, and the movement has more than one cause. I have not measured spam or attribution coverage yet.
Related work
The hand-coded sites came first. This CMS is what got installed underneath them.
 Sanity · GROQ
 Next.js 16
React
 TypeScript
 HubSpot Forms API
 Tailwind
 Static export
The schema carries the funnel role, so no editor has to remember it
I turned down a funnel dropdown. Each type carries the fields its role demands: TOFU types have no gate, MOFU types share a leadGate object, BOFU lives in caseStudy's metrics and quote.
webinar.status moves from upcoming to gated replay to public replay, with conditional fields that validate against each other. The content's funnel role shifts as it ages, without splitting into three types.
Editors pick from 15 named presets, each pre-paired with a safe-contrast text color. Nobody touches hex, so the bar is on-brand and accessible by construction.
Most sites only get attribution when UTMs survive to the form page. I store them on landing and replay them at submit, with the hubspotutk cookie passed alongside.
Build-time GROQ plus static export: no server, no secrets in the bundle, no production CMS calls. Content ships on rebuild, and the publish webhook handles that.
Every type validates its slug, an archived flag soft-deletes, singletons are protected, and one Sanity project per region keeps each region's editor on their own language in an isolated Studio.
Daniel is a professional, knowledgeable individual, that takes pride in the quality of his work. His reliability is second to none and he is always up to the challenge.
 Kathy SongOperations Manager
Need a CMS your marketing team can run without engineering?
Content ops, automation, campaigns and attribution all run on this foundation.